💰 Google AI · Gemini API
Google Gemini API
Pricing
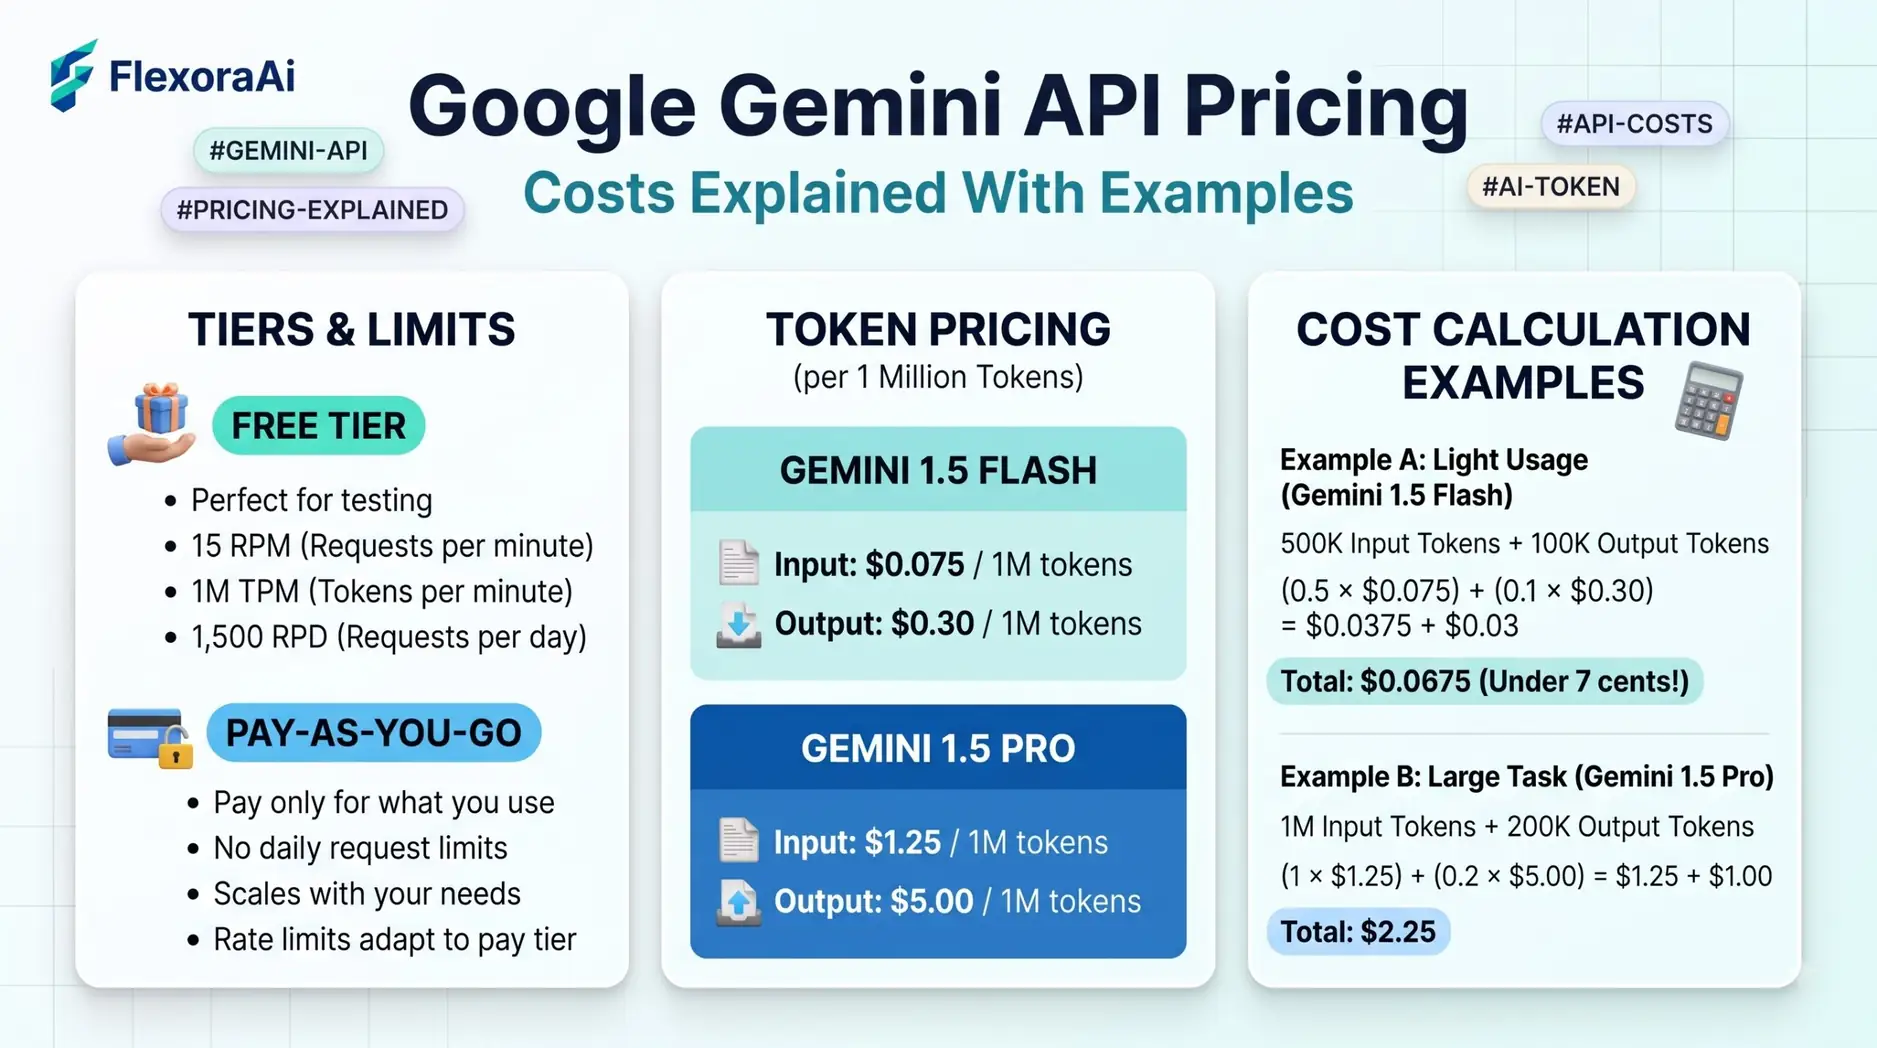
API pricing looks scary until you do the sum. Gemini charges per million tokens, and once you know what a token is, you can estimate a bill in a minute. This guide, part of our Google AI tools guide, explains how the pricing works, gives a worked example with real rates reported in November 2026, and shows the three levers that cut costs.
Short answer: Gemini API costs are billed per million tokens, with separate input and output rates. Google's lineup runs from Flash-Lite for low cost to Pro for hard reasoning. A 50 percent Batch discount and cached-input pricing can cut bills a lot. Always confirm rates on Google's pricing page.
Worth knowing
- Input and output are priced separately, and output includes thinking tokens.
- The free tier has limits, and free-tier content may be used to improve Google's products.
- Batch work costs half, and cached input costs far less than fresh input.
What's a token?
A token is a small chunk of text, roughly three-quarters of a word in English. A 1,000-word article is around 1,300 tokens. The model reads input tokens and writes output tokens, and you pay for both.
The three lanes
| Lane | Use it for | Example rates reported in November 2026 (per 1M tokens) |
|---|---|---|
| Pro | Hard reasoning and complex tasks | About $2 input, $12 output |
| Flash | Balanced speed and cost | Rates vary by version, such as $0.75 input and $3.75 output on one recent model |
| Flash-Lite | High-volume, simple work | About $0.30 input, $2.50 output |
Rates come from tracking sites that were monitoring Google's pricing in November 2026. Gemini models and prices change often, and some older model names have been replaced, so treat these as examples.
A worked example
Say you process 100,000 short requests, each with 1,000 input tokens and 500 output tokens, on a Flash-Lite model at $0.30 input and $2.50 output per million tokens.
| Step | Calculation | Cost |
|---|---|---|
| Input | 100 million tokens × $0.30 | $30 |
| Output | 50 million tokens × $2.50 | $125 |
| Total | $155 | |
| With Batch (50% off) | $77.50 |
A worked sum like this is the sort of practical help that sits beside the playful tricks in our complete list of Google Easter eggs.
Three ways to spend less
- Pick the smallest model that does the job. Test a cheaper model on a sample before you commit.
- Use the Batch API. Google offers a 50 percent discount for work that can wait.
- Cache repeated input. Cached input is billed at roughly a tenth of the normal input rate, but there's an hourly storage fee, so don't cache things you won't reuse.
Watch for hidden costs
- Thinking tokens. They count as output.
- Long context. Some Pro prices change above a certain input length.
- Retries. Failed calls can still cost money.
- Free-tier privacy. Don't send customer data on the free tier.
Plan a small budget
- Estimate average input and output tokens per request.
- Multiply by the number of requests.
- Apply the model's rates.
- Add a margin of 30 percent.
- Set a billing alert before you launch.
If you're comparing providers, our AI tool finder helps you shortlist tools. Other API providers such as OpenAI, Anthropic and DeepL publish their own rates.
Which model should you start with?
| Your goal | A sensible start |
|---|---|
| Learning and testing | A Flash model on the free tier |
| High-volume simple tasks | A Flash-Lite model |
| Hard reasoning or coding | A Pro model, tested on a small sample |
| Large batches that can wait | Any model with the Batch API |
Start small and measure real usage before you scale. Many projects find that a cheaper model handles most requests, with a stronger model reserved for the hard ones.
Keeping an eye on prices
Prices and model names changed several times in 2026, including the arrival of new Flash versions and the retirement of older names. Bookmark Google's pricing page and check it when you plan a budget. If a model you use is deprecated, your calls may be routed to a newer model with a different price.
Set a billing alert and review usage weekly while you're building. A loop that calls the API too often is the most common cause of a surprise bill.
How we checked this: We used Google's pricing page as it appeared in search results, plus several trackers dated between May and November 2026, and we kept only the structure and figures that appeared in more than one source. We did not verify live prices. AI products change quickly, so check dates and your own screen before you rely on any detail. If something here is out of date for you, email ownerflexora.ai@gmail.com and we will fix it.
Your turn: Estimate the monthly cost of one idea you have. Use the worked example as a template, then cut the cost with Batch.
Good budgeting is a habit, and pricing pages are worth reading every time a model changes.
More tricks to try
Choosing an assistant for research? The Google Gemini vs ChatGPT for search guide is next.